7 Steps to Choose the Right AI Architecture for a Business Application
7 Steps to Choose the Right AI Architecture for a Business Application
Based on industry analysis conducted in recent times, almost 80% of all AI projects fail to go beyond proof of concept or make ROI. This is not because of the AI model used. It is mostly because of poor infrastructure design.
Building a good AI product entails far more than merely using an API key for any of the foundation models like GPT-4. You will need some plumbing in place—data pipeline, compute infrastructure, advanced memory management, and server setup.
Are you a CTO, technical lead, or a founder? Then you understand that you need an AI product to stay ahead of your competition.
But how do you handle the number of structural and infrastructural decisions you need to make while everything around you is rapidly changing—the new frameworks, vector databases, and orchestration tools coming out on a weekly basis? Making the wrong decision in such circumstances can mean sky-high cloud bills, unbearable latency, major security issues, and overall project failure.
The ultimate guide takes you through everything you need to know about enterprise AI architecture. By taking these 7 key steps, you can be guided on how to select an appropriate AI architecture for your business application.
From designing a predictive machine learning application to upgrading an existing legacy application with Generative AI, our experts from Gigmint.AI have got your back to help you monetize these architectural blueprints.
What is AI Architecture and Why Does It Matter?
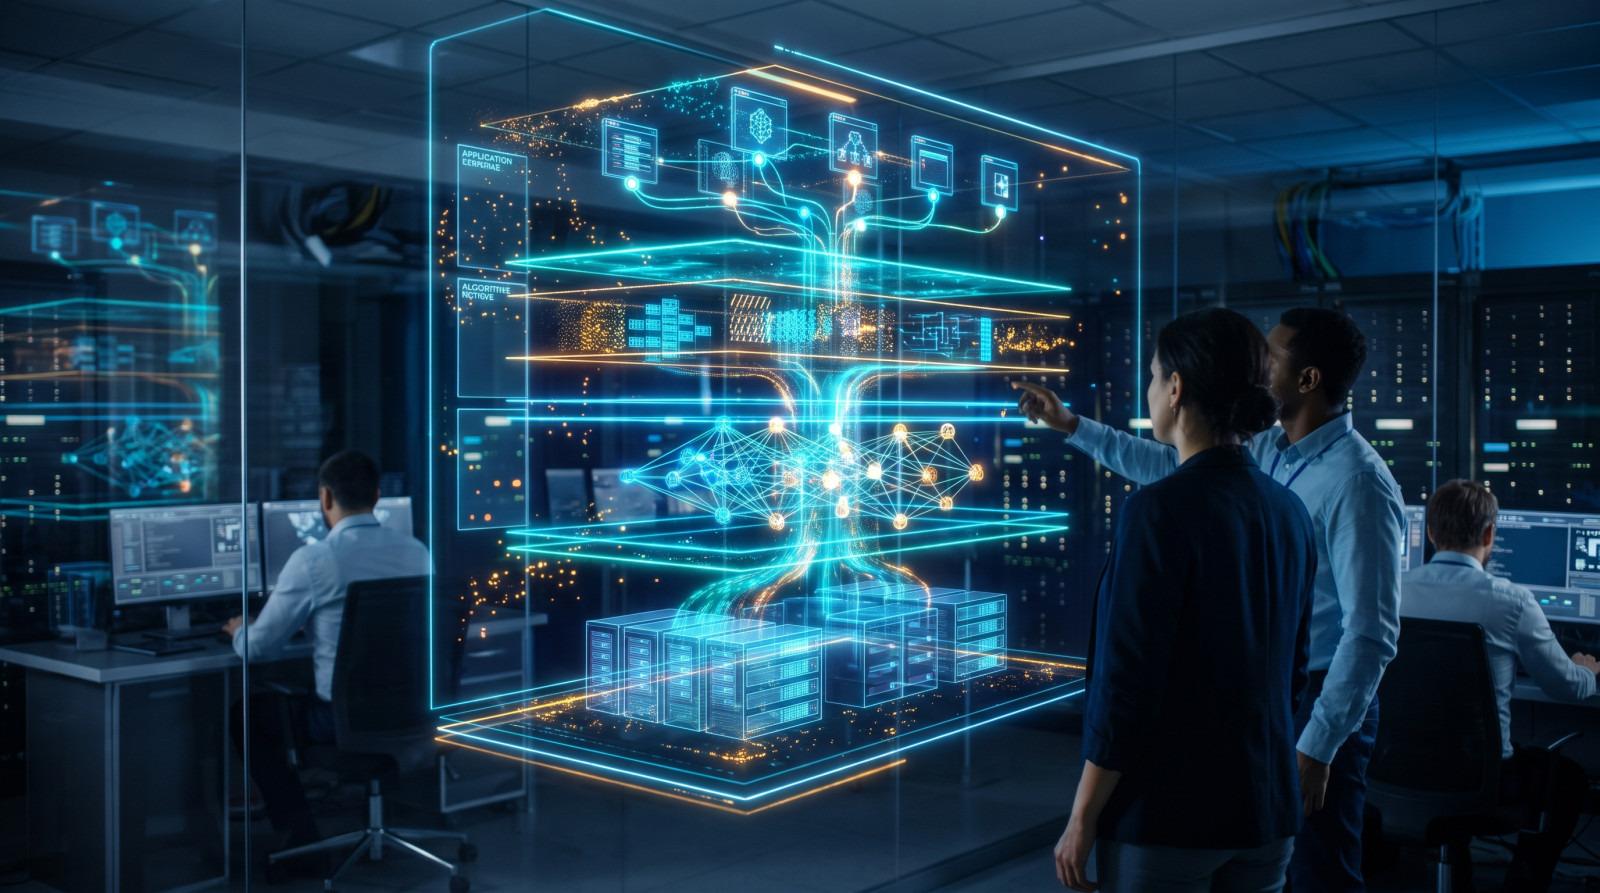
Enterprise AI architecture is the integration of data pipelines, machine learning models, computing hardware (compute), and applications that enable artificial intelligence to operate within the production system.
Enterprise AI architecture is all about creating the complete blue-print for the ingestion of data, processing of data using the machine learning model, and delivering predictions or generation of the output to the user.
Deciding on the type of architecture to use is not just a technical aspect of development; it is an important business decision too. Your choice of structure on day one will have long-lasting effects on three very important aspects of your business, which include:
Latency and User Experience
In today's age, speed is an essential factor. For instance, if the customer service chatbot takes ten seconds to respond because of inadequate inference architecture, the customer will stop interacting with the chatbot.
In the same vein, if the fraud detection chatbot fails to analyze the transaction within fractions of a second, then it becomes futile. With the right kind of architecture, there would be zero latency in serving the models through techniques such as model quantization and edge computing.
Cloud Computing Costs and ROI
The cost of AI, and particularly that of Generative AI and LLMs, is extremely high. Without having the correct AI architecture which helps you maximize the allocation of resources, your cost in the cloud will defeat the gains you achieve using your AI application.
Inadequate architecture will lead to costly GPU clusters being idle at night or improper allocation of resources when handling unimportant prompts. The machine learning process can be improved using caching, prompt routing, and serverless architecture.
Security, Data Privacy, and Compliance
When implementing your AI application within your business processes, you will need to use either your proprietary data or your customers' data (PII). The type of architecture you use will determine if your data is exposed to third parties, subject to prompt injection, or kept within your environment. Correct AI architecture will have RBAC, data masking, and secure enclaves.
Step 1: Define Your Business Use Case and Constraints
It is essential, before moving on to evaluate vector databases, or even starting off with the evaluation of cloud providers or writing a single line of code, to take some time out to define exactly what problem you wish to solve. The type of your business application would determine the very nature of your AI Architecture.
Define the Problem; AI Modality.
A brand new architecture, one of a kind, would be required for each modality. First, it is necessary to describe the basic operation of the system:
Predictive analytics: Predicting quarter sales, identifying failures in equipment or predicting lifetime customer value. This needs tabular data pipelines, feature stores and machine learning models such as XGBoost, random forests.
Generative AI & Natural Language Processing (NLP): Creating marketing content, summarising legal documents and customer questions. This need comes with the need for Large Language Models (LLMs), vector databases and prompt orchestration frameworks.
Computer Vision: Defect detection in the manufacturing process, analyzing medical x-rays and building autonomous vehicles.
Identify the differences between real time and batch processing.
What speed (in seconds) does the AI need to process in order to meet your needs? How fresh is the data that you need?
Batch Processing
It can be applied if the process is done via scheduling. A few examples are the end-of-the-day risk assessment of financials, prediction of the churn rate of customers per month, or classification of many historical records. Batch processes are usually cheaper and manageable as well as ETL.
Real time (Streaming) Processing
This is an important process as real time decisions are required. A few examples are fraud detection of credit cards during purchase, dynamic pricing algorithms in e-commerce sites, or real-time conversations through AI. Real-time processes need complicated software such as Apache Kafka and AWS Kinesis for streaming processing.
Assess Your Operational Constraints
The truth is at the heart of every business. This involves taking into account whether
You can afford to allocate a CapEx budget for investing in on-premises hardware (NVIDIA racks) or you have the flexibility of allocating an OpEx budget because of choosing the pay-as-you-go cloud alternative?
Do you have the technical expertise for MLOps Engineering, Data Science, and DevOps or you would like to go for the easy-to-implement plug-and-play solution provided by the software as a service?
Develop your MVP in four weeks in order to raise investment or you have a year’s time in hand to develop a highly customized moat?
Step 2: Understand the 4 Pillars of Modern AI Architecture
Pillar A: Data Ingestion, Processing, & Storage
Data Flows are crucial parts of the ML architecture design. Your architecture needs to mirror the flow of the data and needs to allow for the transfer of the raw data to the model format.
Data Lakes and Data Warehouses
Unstructured raw data that needs some kind of structuring (traditional data, e.g., SQL databases with sales figures) needs to be kept in the data warehouse (Snowflake, Google BigQuery, Amazon Redshift).
While the unstructured data (e.g., text, audio, PDF files, video logs) needs to be kept in the very scalable data lake (AWS S3, Databricks). The concept of the "Data Lakehouse" has been introduced in modern AI architecture design that is a mix of the best aspects of the two aforementioned types.
Generative AI Models
Today, Generative AI models are being created using RAG (Retrieval-Augmented Generation) which relies on the use of vector databases. The benefit of vector databases is that they allow storing your data in the form of multidimensional mathematical vectors. In this scenario, your LLM can perform semantic search within the necessary data in your documents prior to generating an answer.
Feature Store
In order to create a machine learning model for prediction, a feature store (Hopsworks or Feast) is required.
Pillar B: Model Training & Fine-Tuning Compute
In case when training a model from scratch, fine-tuning an open-source model, or continual training of a prediction model, you need huge computing capacities, in particular, GPUs (Graphic Processing Units) and TPUs (Tensor Processing Units).
Cloud Computing
You can leverage Amazon SageMaker, Google Vertex AI and Azure Machine Learning managed services for greater power from complicated chips like NVIDIA A100/H100 chips. It's the correct approach for most businesses and will not leave the business stale and costing less in maintenance.
Distributed Training
In case of large volumes of data, your system should allow distributed training, where workloads are split between multiple GPUs or clusters via Ray or PyTorch Distributed libraries.
Parameter Efficient Fine Tuning (PEFT)
The modern AI architecture design makes use of PEFT algorithms like Low Rank Adaptation (LoRA).
Pillar C: Model Inference and Serving
The act of making predictions, classifications and generating text from data that the trained machine learning model has not encountered before is called inference. By designing the inference system you use, you can determine how well your machine learning model will produce the output you need for your application via APIs.
Inference Engines
It is not feasible to deploy a super large machine learning model on a normal web server. Some special inference engines like NVIDIA Triton Inference Server, vLLM, and Ray Serve should be used.
These enable to run multiple user requests in parallel, batching (allowing to run several requests in a single batch so you can use more GPUs) and to manage memory effectively in order to prevent your application from freezing due to being overloaded.
Some modern architectures (quantization) are required to run large machine learning architectures into practice. Reducing the precision of the model's weights (e.g., from 16 bits float to 8 bits or even 4 bits): this is called quantization.
Pillar D: MLOps, Monitoring, and Orchestration
The machine learning models change over time as the world changes (this is known as "model drift" or "data drift").
Machine Learning (ML) Continuous Integration (CI) and Continuous Deployment (CD)
It's essential to have MLOps (Machine Learning Operations) pipelines for CI and CD in your architecture to be able to retrain and deploy your models automatically.
Model Registries & Tracking
You need to have either MLflow or Weights & Biases tools, which will enable the tracking of various versions of your models, the datasets that were used to train them, and the metrics of their performance.
LLMOps & Orchestration
For generative AI, orchestration services like LangChain or LlamaIndex are needed to help coordinate the chaining of prompts, retrieve information from vector databases, and enable AI to access external tools like calculators or the internet.
Step 3: Decide Whether to Build, Buy, or Adapt Your AI Model
In Step 3, you will decide whether or not you need to build something, buy something, or adapt something.
It may well turn out to be one of the most critical decisions you make about your AI architecture in your business enterprise is how you acquire your foundational model. It varies greatly and depends more on the constraints and objectives.
To purchase (API-Driven / SaaS Solutions).
Uses third-party APIs from providers of the foundational model – like OpenAI (GPT-4o), Anthropic (Claude 3.5 Sonnet) and Google (Gemini 1.5 Pro).
Pros
Great time to market. A proof of concept can be created in a matter of days. No infrastructure management, no hardware to manage and instant access to the most intelligent and state-of-the-art models available.
Cons
You will need to pay your usage in tokens (that can be very expensive when used in an enterprise manner). You're exposing your corporate data to an outside server.
While it's true that many regulated businesses aren't very confident about the assurances of enterprise packages, it's also true that they can make assurances about the confidentiality of data. You're building in "vendor lock-in" to the price and uptime of one company.
Adapt (Open-Source + Self-Hosting)
The combined approach involves downloading large open-weight models (such as Meta's Llama 3, Mistral, Qwen) and then running them on your own cloud. You could also use them along with RAG techniques or fine-tune them for your particular business needs.
Advantages
Full privacy and control over your data. No data will ever move out of your Virtual Private Cloud. No tokenisation costs incurred with typical APIs will be charged. This means you will have a lot more predictable costs of infrastructure. You'll also have your optimised model that will turn into your business asset.
Disadvantages
This technique will require extremely high internal engineering skills; this means that it is necessary to develop the whole of the infrastructure and handle all the GPUs and servers.
Build (Custom Foundational Models)
To train a very large model from scratch from unstructured data.
Drawbacks
The model may be completely new, customized for very specialized industries, e.g., one model that has been built from scratch using only proprietary genomic data, or special legal precedents, or both, and full control of IP.
Disadvantages
This requires huge investments in data gathering, top-notch AI researchers, and huge amounts of compute power. This strategy is only adopted by Fortune 500 tech companies, nation states, and very niche AI start-ups. When it comes to organisations, 99% of them are just a waste of resources in the name of building.
Step 4: Select Your Physical Deployment Environment
What would your business' AI infrastructure look like? There are so many factors related to your deployment environment that will impact how it performs (or won't perform), including latency, security, regulations, scalability, etc.
AI Cloud-Native Architecture
Applications for modern day businesses appear to work best when deployed on cloud native deployment environments of cloud service providers such as Amazon Web Services (AWS), Microsoft Azure, and Google Cloud Platform (GCP). You can now have a scalable deployment environment for your AI application in your cloud-native deployment environment.
Elasticity
Auto-scaling groups let you have more GPU instances when there are more users accessing your application, and they let you reduce the number of instances to zero when users aren't accessing your application. This allows you to reach the maximum cost effectiveness over idle machines.
Cloud-Native Ecosystems
The Cloud provider provides you an ecosystem (for example AWS Bedrock) which is very convenient for you to use your Data lake, Security and AI model in your IAM (Identity and Access Management) ecosystem.
On-Premise Infrastructure
For regulated industries such as health care, defense, traditional banking, and telecommunications, data sovereignty may also need to be taken into consideration.
Security & Control
You don't have to put the sensitive data out over the internet and it isn't going to be hosted anywhere on a multi-tenant server. The full control of the server racks, GPU and environment security will be available.
Total Cost of Ownership (TCO)
For many organisations that do intensive AI calculations 24 hours a day, after several years (3-5), they find that the total cost of ownership is cheaper than the cost of leasing from the cloud providers.
Edge AI Architecture
Edge AI is the application of computations with the machine learning algorithms directly at the edge of the hardware, in your phone, the IoT devices or even the camera located in the manufacturing facility, rather than ping ponging between the device and the cloud server.
Latency Matters
When the latency matters and is the difference between life and death – as in the case of an autonomous car deciding whether to stop or not, or a robotic arm navigating its way through the manufacturing facility – there is no room for ping pong between the cloud server and the device. This is the situation where computations have to take place.
Edge AI: Where offline capability is needed
Where offline capability is needed, or connectivity is not good enough (agricultural sensors, ships on the marine route), edge AI will be needed. Besides that, you should also consider the bandwidth charges won't be that high as you are not going to upload videos every day.
Step 5: Evaluate Monolithic vs. Microservices for AI
Integration with the existing business logic (web frontend, users' databases, payment gateways) is one of the key components of the architecture of your solution.
Monolithic Architecture
The monolith AI architecture suggests that the AI model code, API endpoint code and the rest of the code for the logic of your application are closely coupled in the same codebase.
The truth: This might be easier for you to work in while creating a prototype, because it is developed and deployed so quickly, but in general, a lot of limitations will be put on you. If your AI model requires more memory to handle some requests, you'll have to scale-up the entire application using the simple frontend.
Microservices and Containerization
A major shift is observed in today's AI solutions towards the microservices approach. Using your AI model with Docker and its orchestration through K8s allows you to isolate the complex inference engine of your AI from other business logic of your application.
Scalability Independence
In the case when unexpected traffic spikes occur in regard to your AI-powered feature (e.g., your chatbot becomes popular with your website users), you can scale up the containers with your AI model.
Flexibility and Resilience
With modular AI architecture, multiple teams can work at the same time. Therefore, the front-end team can go ahead and change the UI, and the data scientists can deploy a new version of AI. In the case of the failure of AI, it will not impact your user's application.
Serverless AI
The new emerging architecture is Serverless AI Architecture. This architecture is the deployment of an architecture without the need of any underlying infrastructure. Your computer will scale up to infinity as per your requests. The architecture is very cost-effective for occasional traffic, but is limited by the problem of cold start time – the time to boot up the server.
Step 6: Factor in Security, Compliance, and Governance
For any AI framework to be effective for business usage, it should be a secure framework. With AI becoming a part of the industry, and the new guidelines on how to use the data, there is a need for a security framework.
Data Privacy, Anonymization, and Compliance
Applications using EU or California personal information must be in compliance with GDPR and CCPA. Should the task at hand fall under the healthcare industry, then you should follow the guidelines set out for HIPAA.
Data Masking
Your requirement will be that you can preprocess the data you put into your AI model so that you don't have personally identifiable information like names, social security numbers, credit cards and more.
VPC and Private Links
In case you make use of cloud APIs in your architecture, you will need to run your architecture using private network links such as AWS PrivateLinks to prevent your data from crossing the public internet.
Protecting Against AI-Specific Cyber Threats
With Generation AI comes Cybersecurity threats that are undetectable by conventional Firewalls.
Prompt injection
This is where an attacker will trick the LLM into disregarding its instructions and therefore leak prompts and other details about how the system works and/or create unintended outputs. An LLM firewall or input validation layer (NeMo Guardrails) will be required.
Federated Learning
If the systems to be implemented are extremely sensitive, some very high-level architectures have been developed, and Federated Learning is one of them. Architecture: In this architecture the base model will be downloaded to the user's local computer (smartphone).
The training is performed locally based on the data owned by the user, that is, never shared. The weights in the mathematical model are updated only on the central server for updating the global model. No content goes anywhere to the cloud.
Auditability and Explainable AI (XAI)
Proper logging capability should be there in the enterprise architecture. It should be possible to log the exact prompt given to the AI, the data that it has retrieved from the vector database and the result that it has returned. XAI is also required for troubleshooting and to explain the reasoning behind the decisions of the AI to auditors, lawyers, and customers.
Step 7: Future-Proofing with AI Agents and Multi-Model Routing
The pace of development of AI technology is such that within the next twelve months, the model which currently looks like the most advanced model gets outdated and becomes a thing of the past. In such circumstances, the ideal way to develop an AI model would be to create a flexible and agnostic one.
LLM Routing Gateways
Do not use a particular AI model, like GPT-4, in your application code. Rather, use API Gateway or LLM router. It will be able to analyze the request and then send it to the right AI model based on the complexity and cost of the task.
The question "What are your business hours?" is a simple question that can be answered by an efficient and cost-effective AI model, like Llama-3-8B. On the other hand, a more complicated question like "Analyze this 50-page pdf file to look for any anomalies" should be passed to an extremely powerful AI model like Claude 3.5 Sonnet.
To get ready for Agentic Workflows.
The next level for AI in the business is a movement from the present stage where chatbots are applied to agentic AI that can reason, plan actions and execute multiple actions on behalf of the user.
To be ready for the future you'll need to build the API architecture so you can communicate with your agentic AI in a secure manner. This type of AI will be able to ask for data from your SQL database, send emails using your CRM, as well as execute codes in a sandboxed environment. Having developed this kind of architecture with strong APIs will help you easily integrate with agentic AI.
Continuous Evaluation
Lastly, but most importantly, you should use continuous automated evaluation of your model which means that it will be evaluated on a daily basis based on a golden dataset in order to keep its capability.
Call to Action
For any specific situation, choosing the right AI architecture is a fine line between latency, cost, and security. There is no single silver-bullet AI architecture
With the right specification of your business case, understanding of the basics of the data and computing infrastructure, sourcing, deployment and security, you will be able to develop something that will add value to your business.
You don't need to be dissuaded from developing your AI solution by infrastructure limitations, unnecessary costs, or any issues with security. You may get assistance from Gigmint.AI technical experts in auditing your infrastructure, migrating from API-based MVP to your own hosted and open source solution, and developing at enterprise level.
Frequently Asked Questions (FAQ)
Which AI architecture is the most cost-efficient one for small businesses?
In order to achieve cost efficiency when building AI models for small businesses, it is necessary to use API-based or serverless architecture. It means that you do not need to buy expensive hardware, because with the help of fully managed services (OpenAI API, Anthropic, or AWS Bedrock), you will only pay for the consumed resources and tokens.
What is RAG (Retrieval-Augmented Generation)?
It is a particular architecture that helps to increase the quality of the response from the LLM by using proprietary knowledge sources outside the model's pre-trained memory. With the help of a vector database, this architecture searches through your company's documents and finds the relevant data to feed it to the LLM in order to receive a highly-precise response.
How does data architecture affect the performance of AI?
The performance of AI is affected by the speed, quality, and relevancy of the data fed into the system. Data architecture ensures proper data flow for accurate results and reduces model biases. Well-optimized data storage like vector databases ensures fast results in terms of data retrieval. Poor data architecture leads to poor processing speeds, inefficiency, AI hallucinations, and failure of the application.
How is AI infrastructure different from AI architecture?
AI architecture is an idea or design behind the software or data pipelines, models, and security protocols needed to solve a certain business problem. In other words, it is the blueprint of the AI solution. AI infrastructure, on the other hand, is the hardware needed to implement the architecture.
Why is Kubernetes preferred in AI deployment models?
Kubernetes is preferred in AI deployment models since it allows for microservices orchestration. This allows businesses to containerize the AI models, meaning the AI inference engine is decoupled from the web app. In case an AI feature becomes viral, more containers will spin up to cope with the GPU load without causing the entire software infrastructure to crash.