How to Build a High-Performance Distributed AI Development Team
How to Build a High-Performance Distributed AI Development Team
The era of AI has now officially arrived and is powering the engines that drive modern business strategies. With businesses from all industries vying to incorporate large language models, Generative AI, computer vision, and predictive machine learning into their products and services, they are all facing a hard, undeniable truth: the rising shortage of AI talent on a global scale.
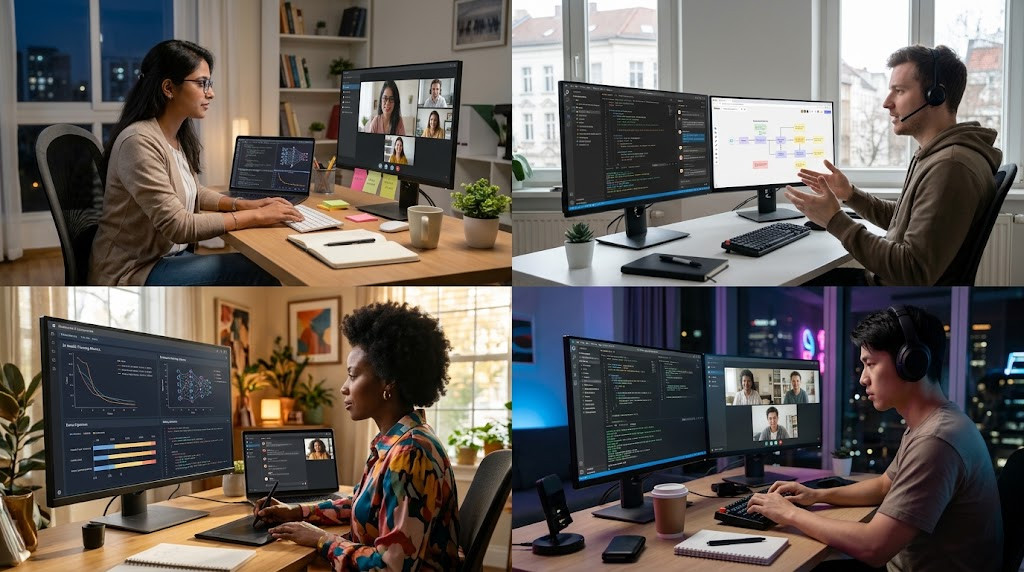
Building a Distributed AI Development Team is becoming an effective solution for companies struggling to access the specialized expertise needed to compete in today's AI-driven market.
The efforts to create a co-located team of AI specialists within the competitive tech centers of Silicon Valley, London, New York, or Toronto will become less and less realistic in the coming time.
As far as new businesses and ventures are concerned, the conventional method for hiring employees does not work well anymore. It is an extremely slow process, highly expensive, and restricts your ability to use global intelligence resources.
A Distributed AI Development Team allows businesses to overcome these recruitment limitations by accessing qualified specialists regardless of their geographical location.
Bidding for a Machine Learning Engineer in San Francisco has driven up salaries and equity packages to astronomical heights, with many projects being left under-resourced.
Shifting from a conventional software engineering group with physical locations to a distributed AI group is far more complicated than creating a couple of Slack channels, issuing MacBook Pros to people, and scheduling Zoom meetings.
There are fundamental differences between AI development and traditional web and mobile application development. AI development involves lots of research, relies on massive data sets, is very probabilistic, not deterministic, and requires heavy infrastructure in the cloud. To coordinate all this, a whole new strategy is needed.
A successful Distributed AI Development Team requires specialized management practices that account for the research-intensive and computationally demanding nature of artificial intelligence projects.
We will explore the specifics of building an effective distributed AI team, including the roles you need to hire, the technologies and MLOps-focused tools required to coordinate a globally distributed workforce, the methodologies suited to asynchronous machine learning research, and how intelligent talent acquisition platforms such as GigMint.ai can accelerate the process.
We will consider the roles you have to hire, the technologies, the MLOps-focused stack that will enable you to synchronize your globally distributed team, the methodology adapted for asynchronous machine learning research, and how you can leverage intelligent talent acquisition platforms such as GigMint.ai to speed up your project significantly.
The Shift Towards Distributed AI Engineering (Why Now?)
For the reasons why the distributed, borderless approach is an unequivocal future of AI development, we need to first analyze the macroeconomic trends and technology changes shaping the modern tech market environment.
The growing adoption of a Distributed AI Development Team reflects how businesses are adapting their hiring strategies to the global demand for advanced AI expertise.
AI Talent Shortage in the World and the Co-location Pitfall
The demand for deep expertise in areas such as neural networks, NLP, reinforcement learning, and computer vision is significantly outpacing the supply of qualified professionals entering the workforce through universities and technical training programs. As recent industry researches have found, although the demand has grown exponentially, the number of skilled professionals remains limited.
If you try to hire the engineers within the 30-mile area from your location, you are going to enter into a zero-sum game with the tech giants who have infinite pockets, compute power, and brands.
With the use of distributed architecture, you will instantly overcome the geographical trap. This means that your pool of talents now comprises hundreds of thousands of engineers located around the globe, instead of just a few thousand local ones who do not even live near your company and do not wish to move.
Distributed AI Development Team makes it possible to hire specialists from various regions without disrupting a cohesive development plan.
Advantages of a Borderless Approach to AI Development
The ability to create a remote global AI team provides numerous unique advantages that are not only limited to talent availability:
1. Unique Cost Arbitrage and Rapid Scalability Opportunities
The possibility of assembling high-quality talents in technical professions from emerging centers of technology like Eastern Europe (Poland, Romania, Ukraine), Latin America (Brazil, Argentina, Colombia), as well as Africa and Southeast Asia, enables the creation of a sizable, specialized workforce.
Companies may, based on where they source their talents, what skills they possess, and how experienced they are, hire several top-tier artificial intelligence experts from emerging centers of technology for the amount of money needed to hire only one mid-tier engineer from Silicon Valley. As the startup runs out of runway, it is necessary that they form the base model for themselves.
The Distributed AI Development Team helps them achieve this equilibrium of recruitment cost, technical ability, and requirement while maintaining the quality of their AI projects.
2. The "Follow-the-Sun" Productivity Cycle
Model training using machine learning is very computationally intensive. The duration for running model training sessions can be anywhere between hours, days, and weeks, depending on the amount of data and complexity of parameters involved. In the context of a globalized and distributed team, one can reach a state of perpetual 24/7 development.
Scenario Example: A Data Scientist working out of Europe finishes cleaning up a dataset and starts a massive model training run before the end of his workday.
While he is clocking off from work, an ML Engineer working out of Asia starts his shift and keeps tabs on the progress of the training session and the first epoch output results.
This continuous workflow makes a Distributed AI Development Team particularly valuable for organizations managing complex model training and development cycles.
3. Diversity of Thought and the Mitigation of Algorithmic Bias
The development of AI models is greatly affected by the viewpoints, culture, and presuppositions of the developers, trainers, and validators of the model.
There will be a greater likelihood of developing biased models that would perform poorly when confronted with diverse real-world populations when there is a homogenous development team, both culturally and geographically. The very nature of being distributed provides a team with diversity in terms of language, culture, and locality. This diversity is not merely a corporate statistic but an absolute technical requirement as well.
Blueprint of a High-Performance Distributed AI Team
One of the typical mistakes which engineering managers often commit is trying to use the exact same strategy of employing people on an AI project which is used for a full-stack web development project. Hiring a "Full-Stack AI Developer" will not yield an enterprise level LLM application.
It is essential to have a well-defined structure in order to make an AI Distributed Development Team effective.
An AI project development process is a combination of scientific research, math, data engineering, and software engineering. For going from data science to application development, it is necessary to strike the right balance of skills in the ecosystem.
Core Roles to Hire for Your Distributed Unit
In order to create a high-performing, autonomous distributed unit, you need to carefully fill in the following fundamental archetypes:
1. Data Scientists/AI Researchers (The Architects)
These are the mathematicians of your enterprise. These people do exploratory data analysis (EDA), intricate algorithm development, feature engineering, and choose optimal neural network architectures (such as choosing the right architecture - Transformer or Convolutional Neural Network depending on the nature of the data).
This kind of work is highly experimental and statistical in nature, and they produce very messy exploratory code in Jupyter Notebooks. They show that the problem can be solved in a mathematical sense.
2. Machine Learning (ML) Engineers (The Bridge)
While researchers are busy developing the most accurate models possible, ML Engineers take care of scalability, latency and efficient use of resources. They take the unstable prototype models and turn them into scalable, clean and optimized object-oriented code.
They optimize algorithms for the particular hardware (Nvidia GPUs, Google TPUs) and develop the interfaces which enable other parts of your software stack to communicate with the AI.
3. Data Engineers (The Plumbers)
It doesn't matter how great a machine learning model is if you don't have a constant and good flow of data. The most important foundational hire would be a Data Engineer.
Data Engineers are responsible for the development of the data pipeline (ETL/ELT process), which scrapes and ingests large datasets from many different sources into central data warehouses or data lakes. Without Data Engineers, you will have your Data Scientists wasting 80% of their time on manually cleaning spreadsheets.
4. MLOps Engineers (The Operational Backbone)
Machine Learning Operations, similar to DevOps for conventional software, is an area that is responsible for managing the cloud infrastructure needed for running machine learning models in production.
Over time, machine learning models may experience declining performance as real-world data distributions and underlying relationships change, a phenomenon commonly associated with data drift and concept drift.
MLOps engineers create CI/CD pipelines for models, set up monitoring dashboards and alerts in order to be notified when your model starts becoming inaccurate in production.
5. AI Product Managers (The Visionaries)
An incredible AI application that does something that is not needed by anyone in reality is a total wastage of resources. To be able to become an AI Product Manager, it is crucial to have a certain skill set because not only do you need to know all the ins and outs of machine learning, but also of business and users' needs.
Quick Reference: Role vs. Primary Responsibility
|
Role |
Primary Technical Focus |
Key Deliverable |
Primary Tools |
|
AI Researcher |
Discovery, Statistics, Mathematics |
Trained prototype model with high F1 score/accuracy |
Python, PyTorch, TensorFlow, Jupyter |
|
ML Engineer |
Scaling, Optimization, API Design |
Low-latency inference API, Refactored Code |
Python, C++, FastAPI, ONNX, TensorRT |
|
Data Engineer |
Architecture, Pipelining, ETL |
Clean, accessible data warehouses/lakes |
SQL, Spark, Kafka, Airflow, Snowflake |
|
MLOps Engineer |
Deployment, Monitoring, Infrastructure |
CI/CD pipelines, Drift alerts, Containerization |
Docker, Kubernetes, MLflow, AWS SageMaker |
|
AI Product Mgr. |
Strategy, User Alignment, Roadmapping |
Product roadmaps, AI feature specifications |
Jira, Notion, Amplitude, Figma |
Sourcing and Vetting Elite Remote AI Talent
Understanding what sort of roles you need is only half of the equation. This is where things start to get difficult. When it comes to finding candidates for specialist technical roles in AI, an entirely different approach is needed.
Finding the right specialists is essential because every Distributed AI Development Team depends on having people with the technical expertise and communication skills to work effectively across geographical boundaries.
Looking Beyond Traditional Academic Resumes
With the fast evolution of AI, educational qualifications may not be enough to evaluate the abilities of the applicant. The experience and performance matter. In some cases, the education obtained five years ago does not cover the most recent AI architectures. When you look for the best candidates at a distance, you need to consider the following examples of practical experience:
GitHub repositories: The candidate’s GitHub repository should contain documented code and contributions to open-source projects related to AI (e.g., PyTorch, LangChain, Hugging Face Transformers, or LlamaIndex).
Kaggle Rank: If the applicant is an expert in the field of data science, you can use the information about their ranking in the competitions as well as participation in those to assess their practical skills.
These competitions involve solving data problems under some computational and resource constraints. Reaching the Grandmaster or Master levels in Kaggle indicates high technical and analytical skills.
Hugging Face Contributions: While looking for the individuals who have knowledge about NLP, Generative AI, and LLMs, you can also consider their involvement in the community of Hugging Face.
Evaluating Technical and Soft Skills in a Remote Environment
A synchronous algorithmic whiteboard interview (where you have a candidate do some kind of task such as flipping a binary tree during a Zoom interview) is notorious for its inefficiency when trying to evaluate machine learning abilities. The creation of AI involves many analytical operations rather than just trivia.
But what the proper way would be, is to conduct an asynchronous take-home dataset assignment. Assign a candidate to construct a prediction model within 48 hours or fine-tune a small open-source LLM from an incomplete and messy anonymized dataset. Here, you should pay attention to:
How do they treat the data – were they blindly applying a complicated NN or spent some time understanding the data distribution and handling missing values?
How detailed and understandable is their documentation? Were they documenting their reasoning and explaining their hyperparameters and failures?
Soft skills are also critical for a remote candidate. Remote AI teams work mostly asynchronously and depend on written communication. If a candidate who should be extremely technical in nature fails to clearly explain in a written document their reasoning behind a loss function or architecture choice, they will significantly hold back the entire remote team.
Leveraging GigMint.ai for Seamless Sourcing
Building this comprehensive vetting process, developing take-home test questions, and procuring on a global level takes months – valuable time which your competition is spending on training its models and gaining market share.
This is where the biggest competitive advantage of GigMint.ai comes into play.
GigMint allows you to bypass the high cost and friction of global hiring and brings you in direct contact with a carefully chosen, elite network of vetted AI talent.
Rather than having your HR department go through hundreds or even thousands of resumes from unqualified candidates or trying to figure out how to gauge the complex MLOps skills of an individual, with GigMint you will have access to elite Data Scientists, ML Engineers, and AI Product Managers, all of whom have been put through extensive domain-specific technical and communicative assessment.
With the use of GigMint.ai, you will be able to get the best possible talent quality and reduce the hiring time from several months to several days, which will enable you to build a fully functional distributed AI team in just a few days.
Working with a specialized talent platform can help businesses establish a Distributed AI Development Team faster while maintaining the technical standards required for successful AI projects.
The Essential Tech Stack for Remote AI Collaboration
The distributed AI team will not only struggle but won’t be able to survive without the right technical stack beyond Slack, Jira, and Zoom. The pain of remote work gets multiplied several times by the pain of dealing with terabytes of training data and maintaining fragile versions of machine learning models.
Collaborative Data & Model Management (The "Git for AI")
While in traditional software development the Git system monitors changes in the source code as well as other version-controlled files, in AI development, reproducibility needs to be ensured through tracking of changes in datasets, machine learning models, and experiments' settings.
Systems like DVC and MLflow support Git by offering additional features aimed at managing data versions, models, and experiments. If a great outcome is achieved by the scientist in Berlin, it has to be reproduced by the developer in Tokyo.
DVC (Data Version Control): DVC helps remote teams log and version control massive datasets and machine learning models as well as the code. In this way, it guarantees that all researchers in the world use exactly the same data split, thus solving the issue of "it works on my machine".
MLflow & Weights & Biases (W&B): MLflow and Weights & Biases (W&B) are mandatory tools for experiment tracking from distance. If the data scientist executes 100 versions of hyperparameter optimization scripts, the tool will automatically log all metrics such as loss function, accuracy plot, and system performance, offering an excellent cloud interface that will allow an engineer to track configurations asynchronously.
Feature stores (Feast, Hopsworks): The repository where data engineers keep their cleansed data. This way, data scientists who use it remotely will not duplicate their data preparation codes.
When the correct technology stack is used, the Distributed AI Development Team will be able to exchange datasets, record experiments, and replicate results without any delay.
Cloud Compute and Infrastructure Democracy
Distributed teams require democratized, secured, and highly controlled access to powerful computational resources (especially GPUs). It is impossible to send A100 GPUs to developers’ houses worldwide.
Platforms such as AWS SageMaker, Google Vertex AI, and Azure Machine Learning will help you create unified cloud environments. They enable remote developers to launch GPU-powered Jupyter notebooks, train models, and shut down computing resources when they are no longer needed, helping organizations optimize infrastructure costs by paying only for the resources they use .
Containerization (Docker & Kubernetes): This is a necessity for remote deployment. It is necessary to make sure that the development environment of everybody is exactly like the server environment.
Asynchronous Communication and Tools for Deep Work
As AI development suggests "deep work" and significant computation time, all possible meetings should be held in a synchronous mode.
The process of asynchronous documentation should be set up via a good wiki, for instance Notion, Confluence or Obsidian.
All aspects – from experiments and hypotheses to decisions and anomalies – should be documented there because your colleagues will be able to get access to everything straight away even though they will be awake at different times.
Overcoming the Unique Challenges of Remote AI Teams
Despite all its advantages from the finance and strategic perspectives, tech leaders need to proactively solve problems of friction that distributed AI development poses.
1. Data security, privacy, and global compliance
Algorithms for Machine Learning designed bearing in mind their complexity are trained through highly confidential data (sensitive, health-care, financial, behavioral). If the data science team is engaged in various domains, then there is a need for the company to meet the requirements of regulation and compliance (GDPR for Europe, HIPAA for USA, SOC 2).
A secure infrastructure is essential in making sure that a Distributed AI Development Team can work together without compromising any sensitive information.
The solution: You should use Zero Trust architecture. In no way, your data engineers and scientists can access the raw and sensitive datasets and download them to their physical laptops. Instead, you need to provide secure access to remote desktops via services like AWS Workspaces and use cloud-based sandboxes.
This approach reduces the need to transfer sensitive data to individual devices while allowing teams to use controlled cloud environments and synthetic datasets where appropriate
2. The "Research vs. Engineering" Friction (The Valley of Death)
This is the biggest problem that almost any AI team faces. Data Scientists are researchers by nature; they love to play around, fiddle with the data, and achieve the best possible accuracy, which may take as long as needed.
ML Engineers are programmers who need everything to be predictable, planned and executed quickly. If this mismatch happens in the remote setting, it can lead to huge delays, which are usually called the "Valley of Death," when an awesome model never reaches production.
Solution: Strict handover process should be applied. The model’s exact format has to be determined to make sure that the transition of the model from the Research to the Engineering department is going to happen. For instance, teams can set the standards on how to package their production-ready models into Docker containers, use ONNX when necessary, etc.
3. Managing Time Zones and Fostering Psychological Safety
Isolation is the hidden killer of productivity in remote working environments. In addition, developing AI entails an enormous amount of failure. Very few models actually work the first time around. The consequence of isolation amongst remote workers means that failures are likely to be kept secret.
The Fix: Mandate 2 to 4 hours of "core overlap time" wherein key players of the global team are connected in order to solve problems together using high-bandwidth collaboration.
Leadership must intentionally create an environment of psychological safety. Set up Slack channels dedicated exclusively to "failed experiments." Publicize the lessons learned in order that the developer in Europe learns from the failure of the developer in South America.
Agile Methodologies Tailored for Distributed AI
Forcing the traditional agile framework (e.g., Scrum) into the AI process is bound to be a frustrating experience. Traditional software development allows for estimations regarding the time required to develop a log-in screen. In AI development, one cannot make estimations regarding the time it would take for the network to converge on a certain accuracy parameter because it is scientific research.
Adapting the Agile Framework for Machine Learning
Time-Boxing vs. Story Points: Rather than using an arbitrary "story point" allocation, let's time-box it. A remote researcher says: "Devote precisely three days to experiment with the new transformer architecture. Whatever comes out of it in the end—whether a success or failure—we'll stop, analyze, and discuss as a group." In that way, scientists won't explore infinite dead ends.
Asynchronous Daily Stand-ups: Don't hold daily Zoom calls since they're toxic for international time zones. Instead of the regular question "What did you do yesterday?" use specific unblocking questions for an AI researcher: "What is being experimented right now? Are you blocked due to GPU compute limitations or by data quality issues?"
Using flexible agile practices helps a Distributed AI Development Team maintain accountability while allowing researchers the freedom to experiment and discover better AI solutions.
KPIs and Measuring Success in a Distributed Setup
Managers in the case of remote/distributed workers need to move away from input-oriented performance measures (hours worked, code written) to highly specific output-based measures. With regards to AI, there must be harmony between performance in terms of technology and business.
Metrics That Actually Matter in AI
Model Performance & Mathematical Metrics: Measure the exact statistical results you are interested in, based on the nature of your work - for example, F1 for classification, Precision/Recall charts or Mean Absolute Error (MAE) for regression. These results must be measured in an automated fashion using your MLOps tools.
Latency and Inference Time: A model which has 99.9% accuracy but takes 12 seconds to generate one prediction is useless in production. Measure API latency strictly as one of the critical KPIs for your ML Engineering team.
Deployment Time (TTProduction): How much time does it take to transform a great idea from researchers' Jupyter Notebook into a live service? Reducing this time is the ultimate KPI that measures effectiveness of the entire distributed team.
ROI of Infrastructure and GPU Usage: Computing in the cloud is costly. Measure how well your team uses costly GPU instances. Are they left idle at night without shutting down?
Future-Proofing Your Enterprise AI Strategy
As the technology rapidly evolves, those companies that remain stubbornly insular, constrained by only local, intensely competitive talent markets, are sure to rapidly lag behind their more nimble counterparts from around the globe.
A top-performing distributed AI development team will allow you to leverage the best minds available, optimize your development and training processes, and scale your operation with astonishing efficiency. This is going to be a 24/7 push that you simply cannot get with regular teams.
A well-run Distributed AI Development Team can be turned into a sustainable competitive advantage through constant access to global experience and scalability according to evolving AI needs of companies.
But how do you do all that? Not without a proper structure, specific MLOps tools, effective remote management procedures, and – above all – the very best people available. Don’t let geographical barriers, limited local talent, and heavy friction of global HR recruitment hold your company back.
Are you prepared to grow your artificial intelligence potential and get ahead of the rest?
No more problems with local recruitment. Hire your AI development team remotely through GigMint.ai. With direct access to the hand-picked network of Data Scientists, ML Engineers, and AI experts, GigMint.ai assists companies in finding the right talent to kickstart their AI development efforts and overcome recruitment obstacles.